

Listen to this post: SmartRateLimit: An Open-Source Fix for 429 Errors on OpenAI, Anthropic and Other APIs
Last updated: 7 October 2026. Details below come from the project’s own GitHub README and PyPI listing; no independent benchmarks exist yet. Disclosure: Olaverse Lab, which maintains SmartRateLimit, and CurratedBrief share an owner.
The 60-second version
- SmartRateLimit is an open-source Python library from Olaverse Lab that paces outgoing API calls so an application stops hitting HTTP 429 “Too Many Requests” errors, largely by reading the limits APIs already advertise in their response headers.
- It understands standard
X-RateLimit-*headers,Retry-After, and the token-count headers OpenAI and Anthropic return — which matters for AI apps, where the binding limit is often tokens per minute rather than requests. - Limits can be enforced across threads (in memory), across processes on one machine (SQLite) or across many machines (Redis, via a server-side Lua script).
- The latest release is 0.5.1 (3 September 2026), Apache-2.0, Python 3.8+. It is early-stage: pre-1.0, a single maintainer and a handful of GitHub stars.
Why rate limiting got harder in the LLM era
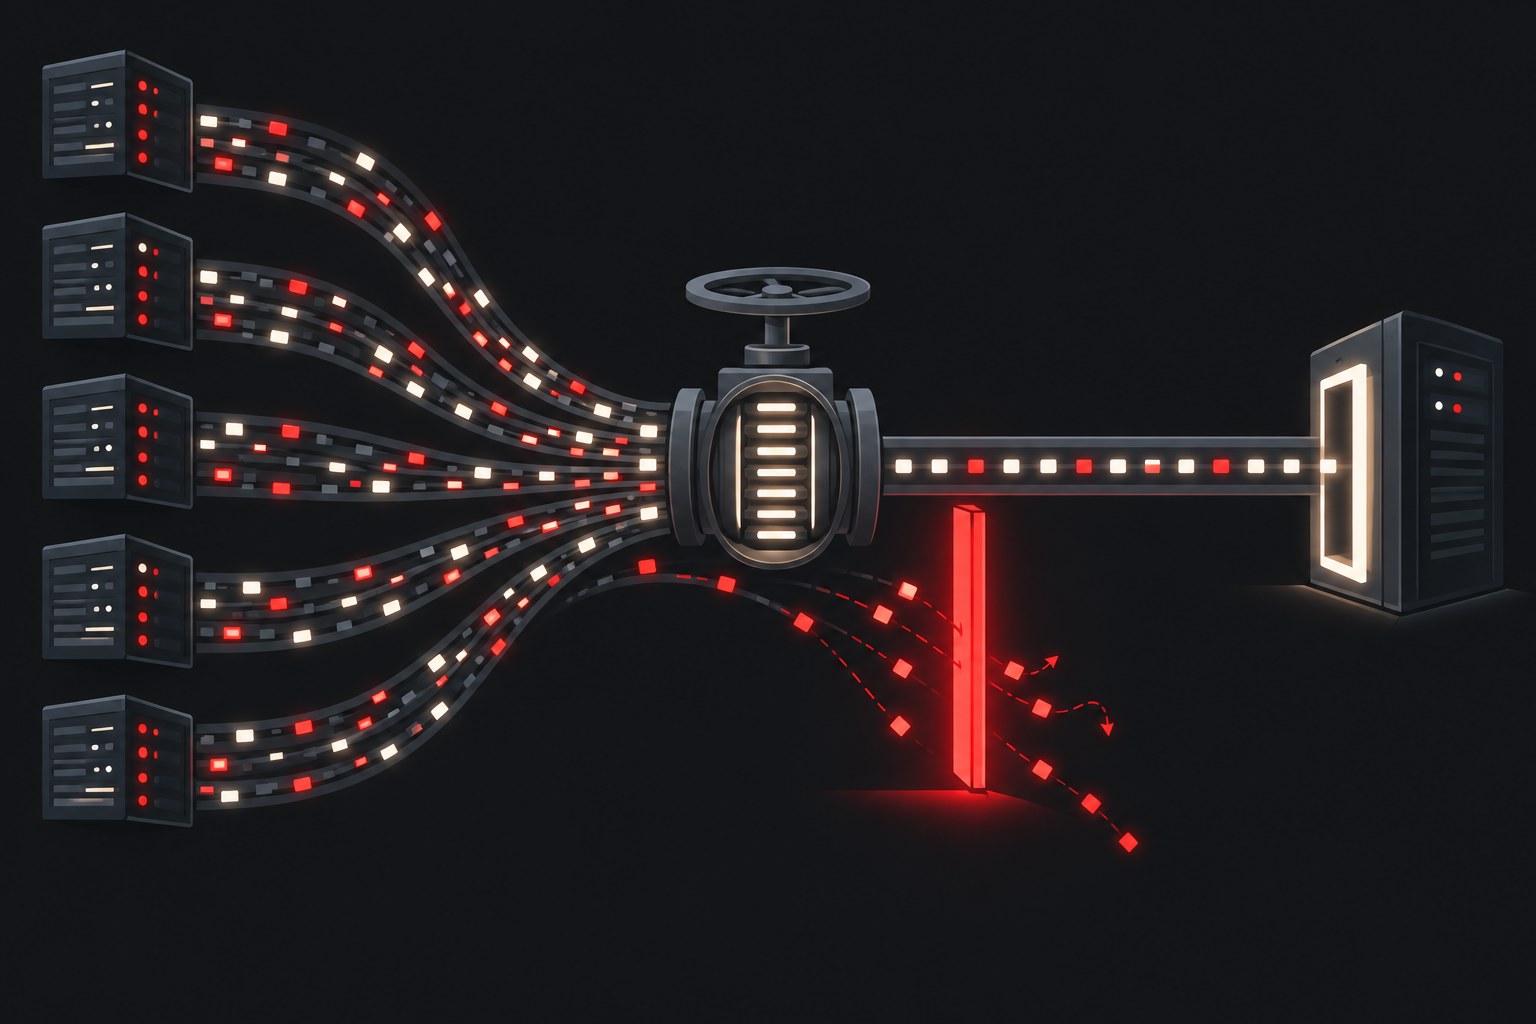
Rate limits used to be simple: a fixed number of requests per hour, documented once and rarely changed. Building on large language model APIs broke that model in three ways. First, the limit that actually bites is frequently tokens per minute, so two requests of very different sizes cost very different amounts of budget. Second, limits are applied on several dimensions at once — requests and tokens, sometimes per model — and exceeding any one of them triggers a 429. Third, agentic and batch workloads now fan out across many workers, so a limit enforced inside one Python process is not a limit at all once ten processes share the same API key.
The usual responses are hard-coded sleeps, retry loops that hammer an already-throttled endpoint, or bespoke middleware rewritten for each project. SmartRateLimit’s pitch is to replace that with one wrapper that learns limits from the API’s own responses and enforces them consistently across however many workers are running.
How it works
The core idea is header detection. Most mature APIs tell clients their quota on every response — how many calls remain and when the window resets. SmartRateLimit parses those headers, including Retry-After in both its seconds and HTTP-date forms, and the token headers used by OpenAI and Anthropic. Non-standard header names can be mapped manually with a headers_map option. Each scope then gets its own token bucket, and calls wait (or, if configured, raise an exception) when the bucket is empty.
The library labels every limit it holds with a confidence level, which is a useful piece of honesty in the design:
| Confidence | Meaning |
|---|---|
confirmed |
The API reported both the limit and its window |
estimated |
A limit was seen but the window was assumed (one hour by default) |
configured |
Set by the developer and never overwritten by detection |
registry |
Seeded from a built-in provider profile, replaced once the API reports its own numbers |
This example, adapted from the README, shows the zero-configuration path alongside explicit limits:
from smartratelimit import RateLimiter

limiter = RateLimiter(storage='sqlite:///rate_limits.db')
response = limiter.request('GET', 'https://api.github.com/users')

# Explicit limits: per path, and on a token dimension
limiter.set_limit('api.example.com/search', limit=10, window='1m')
limiter.set_limit('api.openai.com', limit=90000, window='1m', dimension='tokens')
response = limiter.request('POST', url, json=payload, cost={'tokens': estimated_tokens})
That last call is the AI-relevant feature: a single request is charged against several budgets — requests and tokens — atomically, so it either fits within all of them or waits. Per-path limits follow a “narrowest match wins” rule, so a strict search endpoint can sit under a looser host-wide limit. Async code is supported through httpx and aiohttp, and an existing requests.Session can be wrapped rather than rewritten.
Keeping limits honest across processes and machines
The design choice most worth noting is where tokens are consumed. Rather than reading a counter, deciding locally, then writing it back — which lets two workers both see “one call left” and both proceed — SmartRateLimit consumes tokens inside the storage backend itself:
| Backend | Mechanism | Safe across |
|---|---|---|
| Memory | Consumption under the storage lock | Threads in one process |
| SQLite | BEGIN IMMEDIATE write transaction |
Processes on one machine |
| Redis | Server-side Lua script using the Redis server’s clock | Processes on many machines |
Using the Redis server’s clock rather than each worker’s local clock sidesteps a subtle failure where machines with slightly different times disagree about when a window resets. For teams running distributed agent fleets or batch jobs against a shared LLM key, this is the part that separates a real rate limiter from a polite sleep().
Retries, monitoring and the simulator
By default a call gets up to three attempts, retrying on 429, 503 and 504 responses with jittered exponential backoff; when an API sends Retry-After, that value overrides the backoff schedule, capped at a configurable max_delay. Retries can be switched off entirely. The library exposes status monitoring and Prometheus or JSON metrics, and ships a command-line tool. Its smartratelimit simulate command models which budget will run out first for a planned workload — useful when deciding whether a job will be limited by requests or by tokens before writing any code.
What to be cautious about
- Maturity. At 0.5.1 with one maintainer, two GitHub stars and about 30 commits on its main branch, this is young software. Pin the version and read the changelog before upgrading.
- Fail-open by default. If Redis is unreachable, requests go out unpaced with a logged warning. That keeps an app running but can briefly blow through a limit; the
fail_closed=Trueoption reverses the behaviour. - Estimated windows can be wrong. When an API reports a limit but not its window, the library assumes one hour. The README recommends replacing estimates with explicit
set_limit()calls. - Small provider registry. The built-in table of known provider limits is deliberately small, so many APIs that don’t advertise limits in headers will need manual configuration.
- No published benchmarks. There are no overhead or throughput figures yet, and no third-party evaluation.
For builders
- If your AI app hits 429s on OpenAI or Anthropic, model the token dimension explicitly rather than only counting requests; on LLM APIs, a token budget can run out long before the request count does.
- If you run more than one worker against the same key, any limiter you use must share state — SQLite for one machine, Redis for several — or each worker will assume it has the whole quota.
- Decide fail-open versus fail-closed deliberately. User-facing apps may prefer to keep serving; batch jobs that risk account-level penalties may prefer to stop.
- Try it cheaply:
pip install smartratelimit, with[httpx],[aiohttp]or[all]extras for async and Redis support.
SmartRateLimit sits alongside Olaverse Lab’s other open releases, including its 608-language identification models published this week.
What we still don’t know
- How much latency and overhead the limiter adds per request, particularly the Redis backend under heavy concurrency.
- How quickly provider profiles will keep up as AI labs change their published limits, which happens frequently.
- Whether the project will attract outside contributors and reach a stable 1.0 API.
FAQ
What is an HTTP 429 error?
A 429 “Too Many Requests” response means a client has exceeded the rate limit an API allows in a given window. Well-behaved clients slow down; poorly-behaved ones retry immediately and often get throttled further.
Does SmartRateLimit work with OpenAI and Anthropic?
According to its README, yes: it reads the token-count headers both providers return and supports charging requests against a separate token budget.
Is it free to use commercially?
Yes. It is released under the Apache-2.0 licence.
Does it work across multiple servers?
With the Redis backend, yes. Tokens are consumed inside Redis by a Lua script, so all workers share one consistent budget.
Sources
- GitHub — Olaverse-Labs/smartratelimit (README, primary source)
- PyPI — smartratelimit (release history, version 0.5.1)